Start with what you already know. Let the model learn the rest.
Most systems ask a model to learn your business from scratch. Here you supply the part that is already known: how your business normally behaves. The model only learns what is left over. That is a smaller problem, its mistakes are easier to see, and it works before you have history.
In plain termsA known pattern plus a small learned correction, instead of a model starting from nothing.
State changes for two reasons
Four consequences that matter commercially
Why this beats predicting state directly.
It works before you have much data
The baseline is available on day one because it comes from how your business works, so no history is needed. The learned component starts at zero trust and earns its weight. You get a usable model in the first week.
It degrades gracefully
If the learned component is wrong, the state still moves correctly under baseline dynamics. The failure is a missed correction, and the state stays sensible. A model that predicts state directly is confidently wrong about everything when it is wrong.
Its errors are interpretable
A residual that should have fired and did not is a bounded, visible event: “the model missed the supplier disruption”. You can look at it, explain it and retrain against it. “The model was wrong” is not a debuggable statement.
It gives you a baseline to be measured against
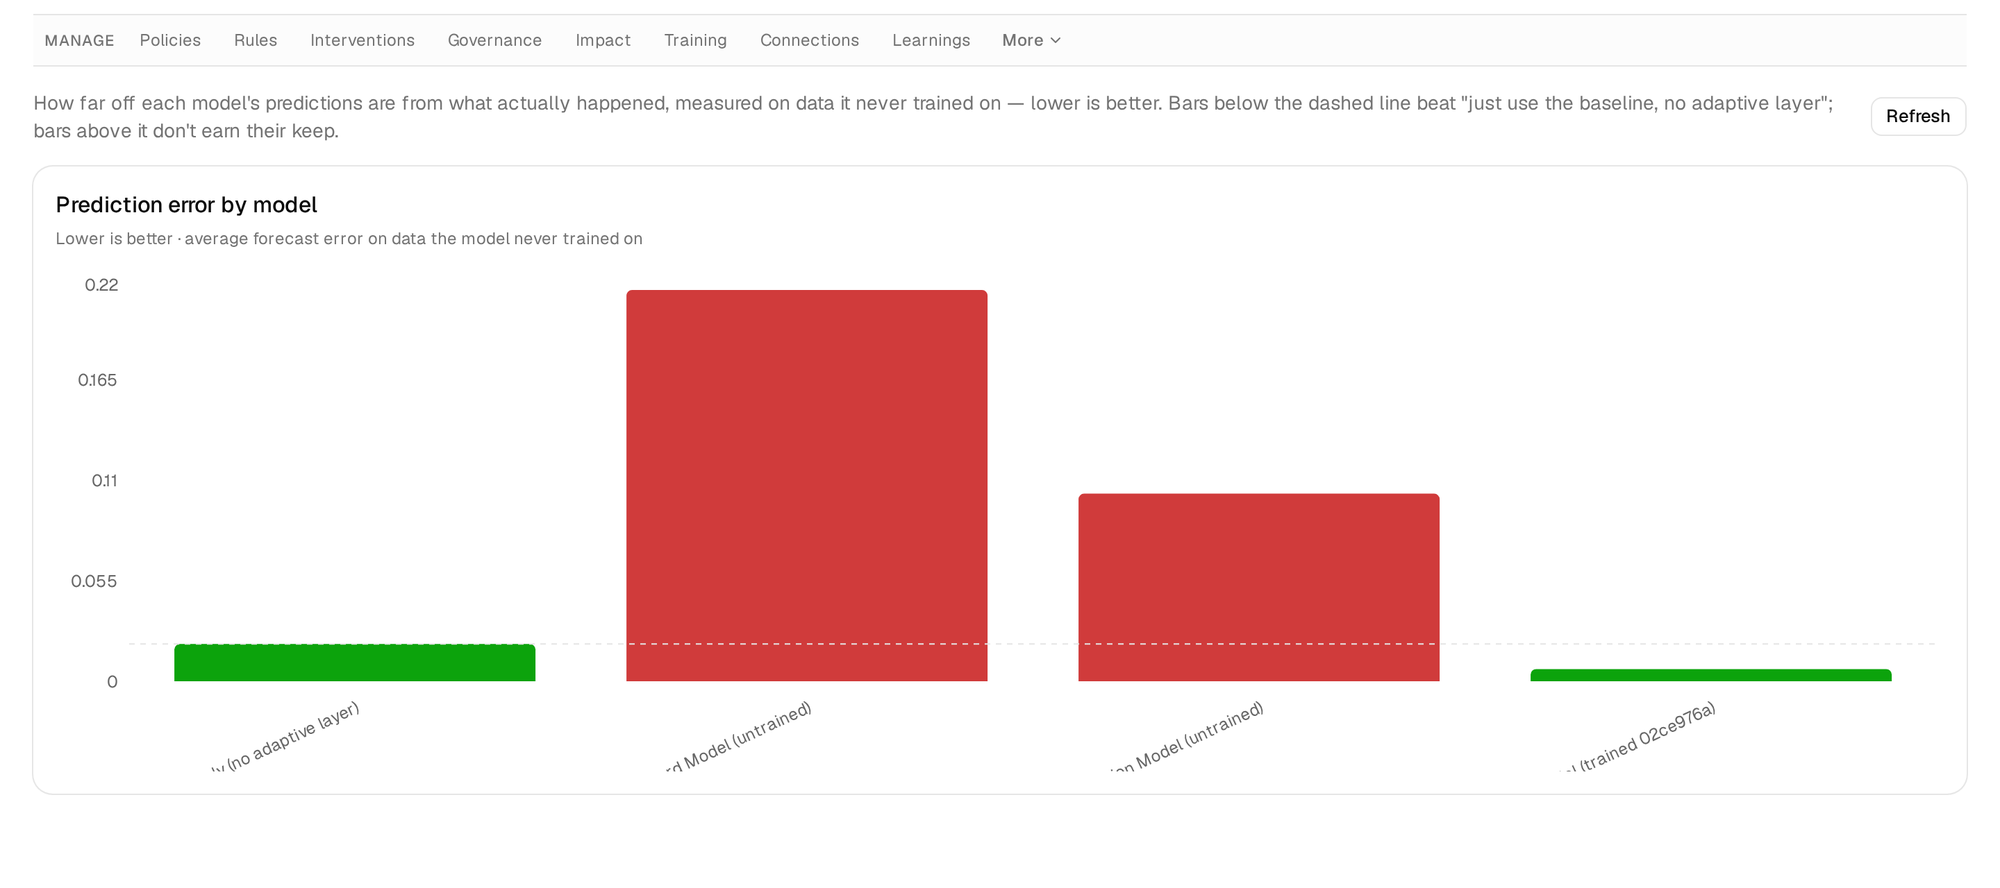
Because the baseline is a real, runnable model, we can answer the question that matters: is the learned component adding anything? If the residual weight needs to be zero to be accurate, the platform reports that. That is the platform working correctly.
The learned component: what kind of model, and why
The correction comes from a specialized, bounded learned component. It is not a language model and it generates nothing: it produces a numeric correction the business can weight, inspect and override.
- Time is a first-class input. State advances by the time that has elapsed (`dt`) rather than a fixed step. The model is asked “how much time passed”, which is the question the business asks.
- Irregular observations are normal. A store that reports every 200 ms and a supplier that reports daily are handled by the same component, because it is parameterized by time.
- Small and inspectable. Its internal signals are small enough to display, so a practitioner can see which dimension the model is leaning on.
- Two variants. A faster, higher-capacity configuration and a smaller, more interpretable one, selectable per domain.
Elapsed time is real elapsed time. In production editions `dt` is the observed time between an entity’s events, recovered from timestamps. In the demo edition, with its built-in simulator, it is a fixed simulated step. Gaps longer than the training ceiling fall back rather than extrapolating, because extrapolating through a data gap is how you produce a confident number with no information in it.
One step of the engine
- The current stateLeads to: Baseline dynamics; Learned correction
- An event: And the time since the last oneLeads to: Baseline dynamics; Learned correction
- Baseline dynamics: How the business normally behavesLeads to: The next state
- Learned correction: Scaled by a configured weightLeads to: The next state (adds)
- The next state
What we avoid, and why
| We avoid | Because |
|---|---|
| Predict state from scratch | A larger learning problem, a worse failure mode, and it needs far more history. |
| Treat every update as an independent sample | State is sequential; ignoring that throws away the signal. |
| Use a fixed step size regardless of real elapsed time | It produces silently wrong timing on irregular feeds. |
| Hide the residual weight | If you cannot inspect how much the model is trusted, you cannot govern it. |
| Retrain on the model’s own output | Self-referential corpora are detected and disqualify a promotion. |
The platform records which source (a model, a rule or a real outcome) produced each training row and flags corpora that are too self-referential to certify. A model trained on its own predictions looks excellent and knows nothing.
The correction has to earn its place
Models are compared with a baseline on data they never trained on. Those that do not beat it are shown.
See the residual weight on a real domain
We will show the baseline, the correction and the weight side by side, and what the model record says about whether the correction earns its place.